Kohei Uehara's Website
About me
I am Kohei Uehara (上原 康平), currently working as a research engineer at Noetra Corp. on secondment from SB Intuitions Corp. since July 2026.I received my Ph.D. in Information Science and Technology from the University of Tokyo in March 2023.
My research interest focuses on machine learning across vision and language, Large Language Models (LLMs) and Vision-Language Models (VLMs), Accessibility, and Human-Computer Interaction (HCI).
Current Positions
- Research Engineer, Noetra Corp. (since July 2026; on secondment from SB Intuitions Corp., where I remain employed)
Work Experience
- July 2026 - Present : Research Engineer, Noetra Corp. (on secondment from SB Intuitions Corp.)
- April 2025 - Present : Research Engineer, SB Intuitions Corp. (seconded to Noetra Corp. since July 2026)
- April 2023 - March 2025 : Assistant Professor, Machine Intelligence Lab., Research Center for Advanced Science and Technology (RCAST), The University of Tokyo
- June 2023 - March 2025 : Part-Time Researcher, Accessibility Lab., Miraikan (The National Museum of Emerging Science and Innovation)
- July 2023 - March 2025 : Visiting Researcher, Machine Intelligence for Medical Engineering Team, RIKEN
- April 2021 - July 2021: NVIDIA, Research Internship
- February 2019 - April 2019 : LINE Corporation, Machine Learning Engineer, Part time job
- August 2018 : Mercari, Inc. Machine Learning Engineer Internship
Education
- April 2020 - March 2023 : Ph. D. student, Information Science and Technology, The University of Tokyo. (Advisor: Prof. Tatsuya Harada)
- April 2018 - March 2020 : Master’s student, Information Science and Technology, The University of Tokyo. (Advisor: Prof. Tatsuya Harada)
- April 2014 - March 2018 : Undergraduate student, Mechano-Informatics, The University of Tokyo. (Advisor: Prof. Tatsuya Harada)
Projects
Asagi - Japanese Vision&Language Model
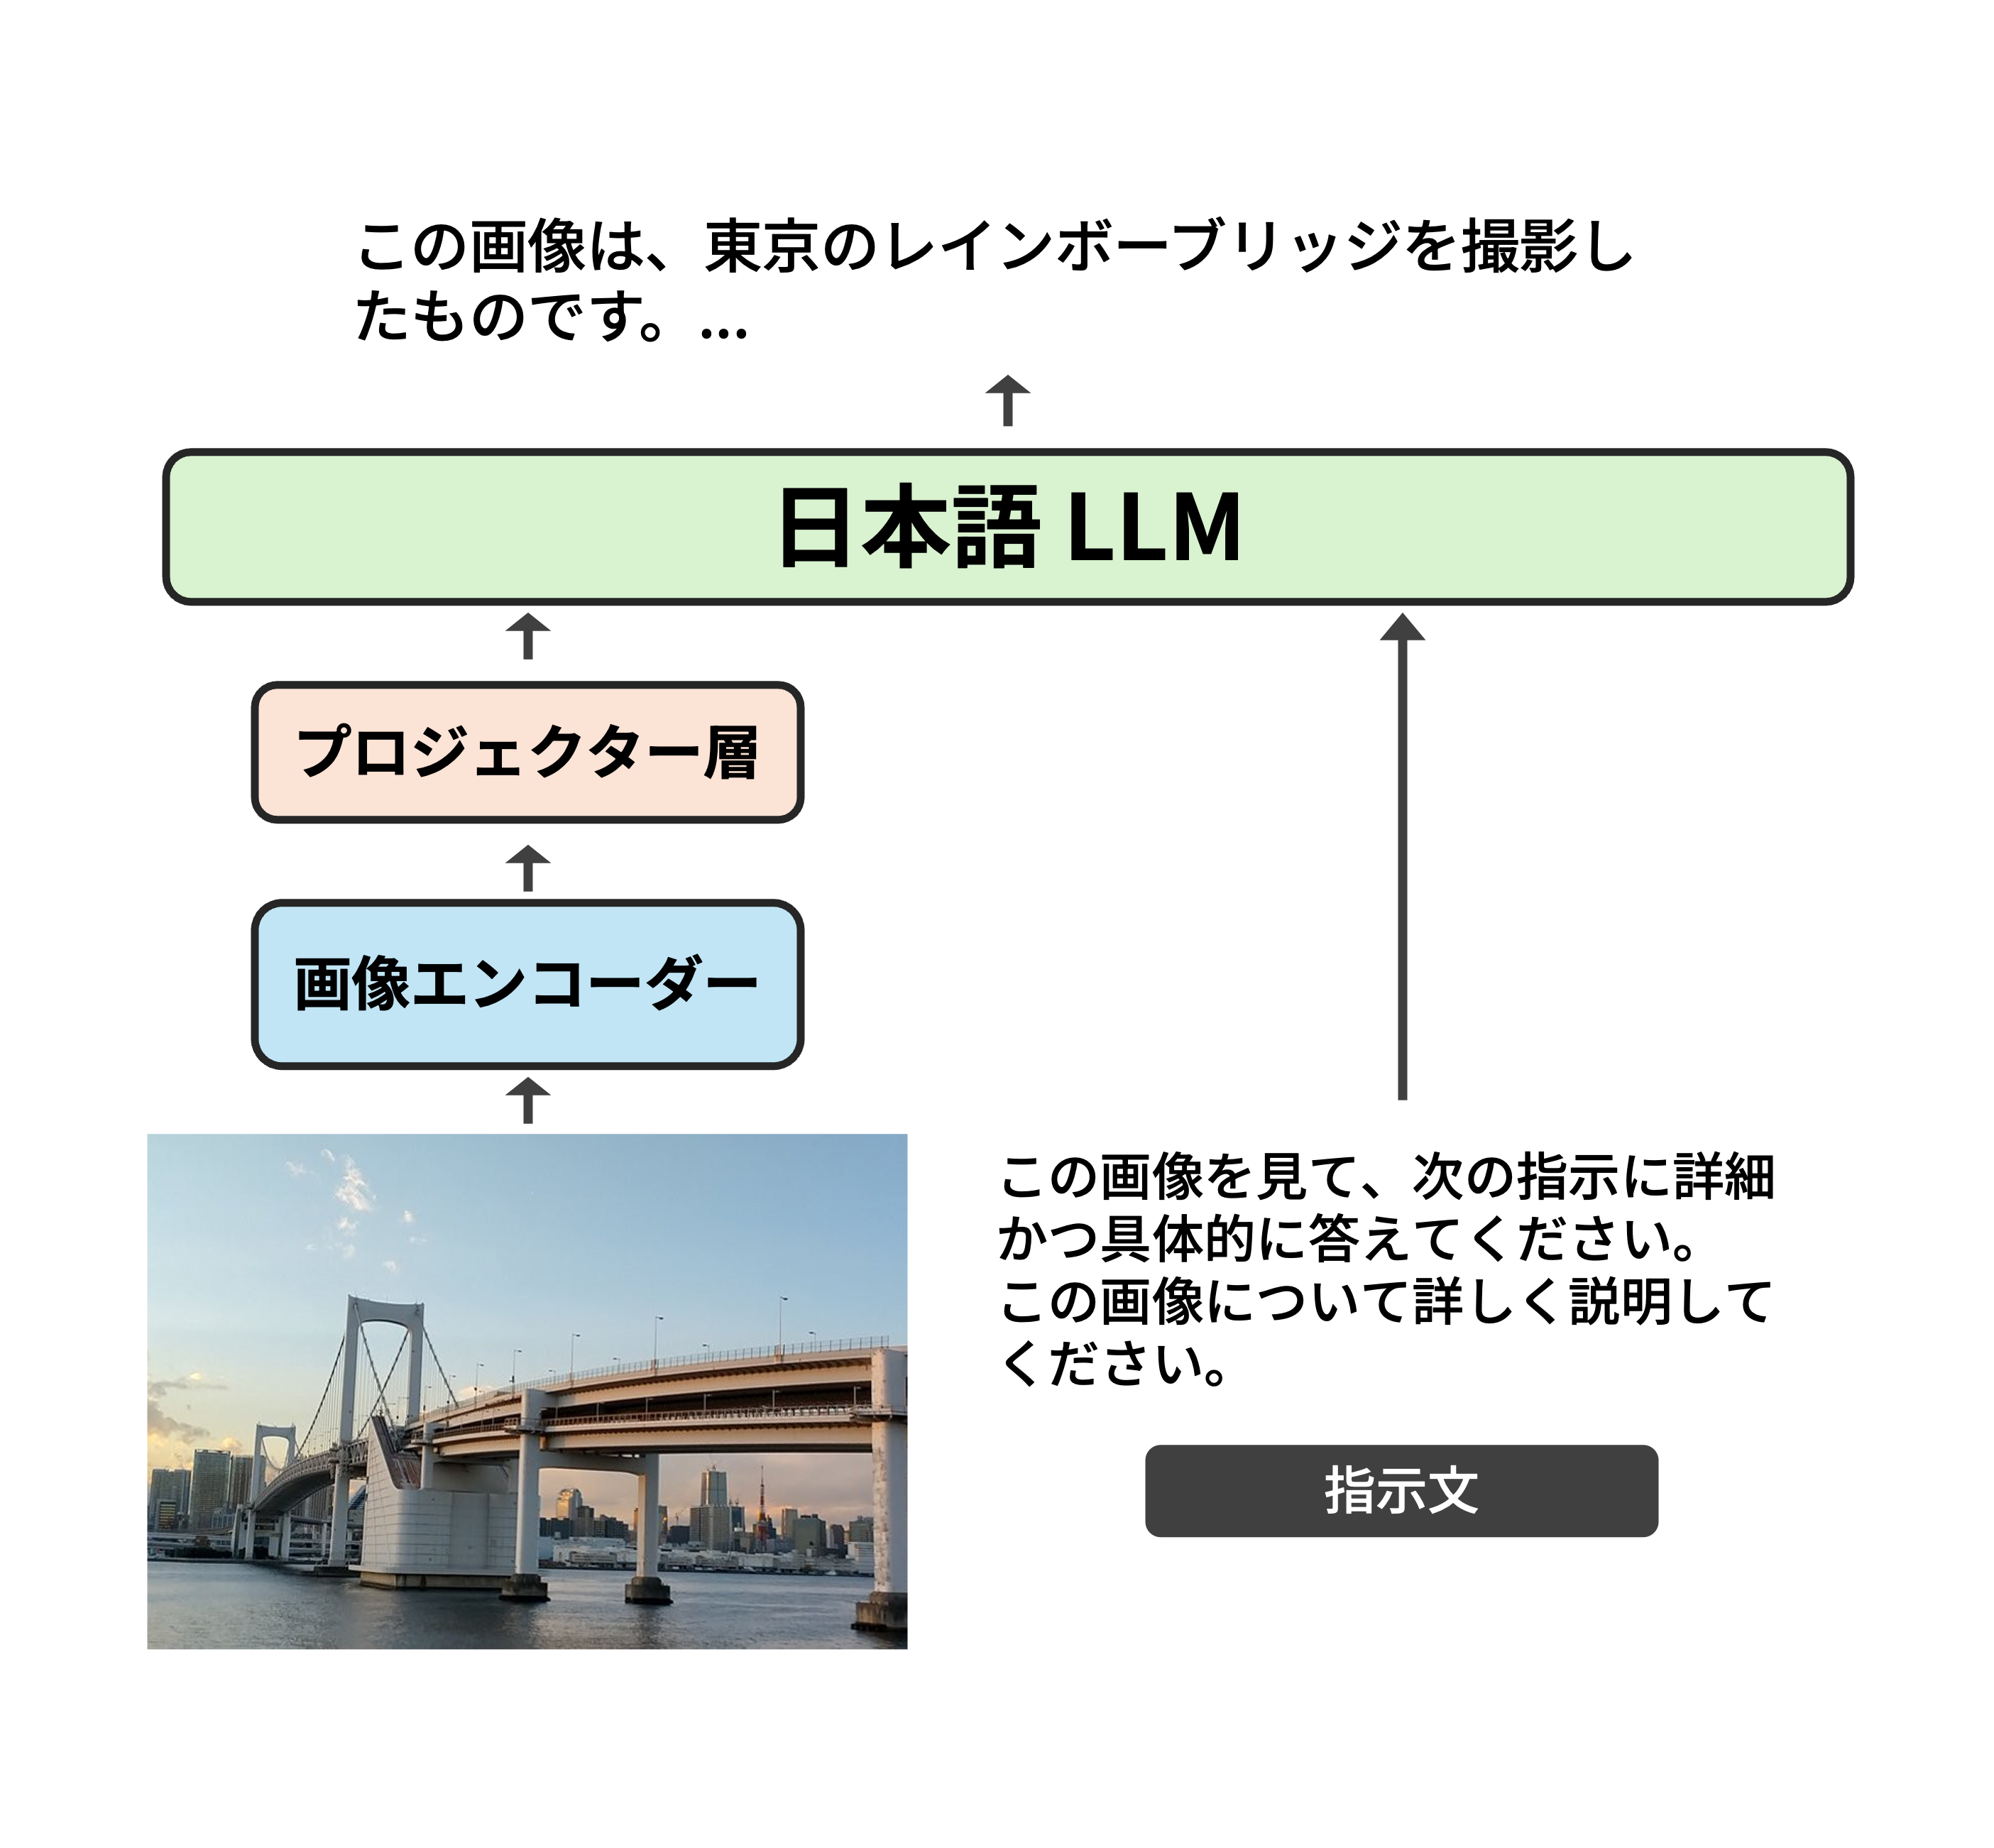
Asagi is a Japanese Vision&Language Model.
The architecture of Asagi is based on LLaVA, which consists of a vision encoder, a language decoder, and a 2-layer MLP for projecting visual features into the language feature space.
We used Japanese LLMs as the language decoder, and the vision encoder is based on the SigLIP model.
We synthesized a large-scale Japanese Vision & Language dataset, consisting of approximately 20 million image-text pairs.
The model is publicly available on the Hugging Face Model Hub.
Please check the project page for more details.
Publications
Journal and International Conference
- NEW Zhongyi Zhou, Kohei Uehara, Haoyu Zhang, Jingtao Zhou, Lin Gu, Ruofei Du, Zheng Xu, Tatsuya Harada. ToolGrad: Efficient Tool-use Dataset Generation with Textual “Gradients”. In Findings of the Association for Computational Linguistics: ACL, 2026. [Paper]
- NEW Toshiki Katsube, Taiga Fukuhara, Kenichiro Ando, Yusuke Mukuta, Kohei Uehara, Tatsuya Harada. DEJIMA: A Novel Large-scale Japanese Dataset for Image Captioning and Visual Question Answering. In Proceedings of the Fifteenth Language Resources and Evaluation Conference (LREC), 2026. [Paper] [Project Page]
- Masaki Kuribayashi†, Kohei Uehara† (†equal contribution), Allan Wang, Daisuke Sato, Renato Alexandre Ribeiro, Simon Chu, Shigeo Morishima. Memory-Maze: Scenario Driven Visual Language Navigation Benchmark for Guiding Blind People. IEEE Robotics and Automation Letters (RA-L), 10(11): 11658–11665, 2025. [Paper] [Preprint]
- Masaki Kuribayashi, Kohei Uehara, Allan Wang, Shigeo Morishima, Chieko Asakawa. WanderGuide: Indoor Map-less Robotic Guide for Exploration by Blind People. In Proceedings of the 2025 CHI Conference on Human Factors in Computing Systems (CHI), 2025. [Paper]
- Kohtaro Tanaka, Kohei Uehara, Lin Gu, Yusuke Mukuta, Tatsuya Harada. Content-Specific Humorous Image Captioning Using Incongruity Resolution Chain-of-Thought. In Findings of the Association for Computational Linguistics (NAACL Findings), 2024.
- Kohei Uehara and Tatsuya Harada. Learning by Asking Questions for Knowledge-Based Novel Object Recognition. International Journal of Computer Vision (IJCV), 2024 [Paper] [Project Page]
- Kohei Uehara and Tatsuya Harada. K-VQG: Knowledge-aware Visual Question Generation for Common-sense Acquisition. WACV, 2023. [Paper] [Project Page]
- Kohei Uehara, Nan Duan, Tatsuya Harada. Learning to Ask Informative Sub-Questions for Visual Question Answering. 5th Multimodal Learning and Applications Workshop (CVPR 2022, Workshop), 2022. [Paper]
- Kohei Uehara†, Yusuke Mori† (†equal contribution), Yusuke Mukuta and Tatsuya Harada. ViNTER: Image Narrative Generation with Emotion-Arc-Aware Transformer. The 1st International Workshop on Multimodal Understanding for the Web and Social Media (WWW 2022, Workshop), 2022. [Paper]
- Kohei Uehara, Tatsuya Harada. Unsupervised Keyword Extraction for Full-sentence VQA. First International Workshop on Natural Language Processing Beyond Text with EMNLP 2020 (NLPBT2020), 2020. [Paper]
- Sho Maeoki, Kohei Uehara, Tatsuya Harada. Interactive Video Retrieval with Dialog. CVPR 2020 Workshop on Multimodal Learning, 2020. [Paper]
- Kohei Uehara, Antonio Tejero-de-Pablos, Yoshitaka Ushiku and Tatsuya Harada. Visual Question Generation for Class Acquisition of Unknown Objects. The 15th European Conference on Computer Vision (ECCV2018), 2018. [Paper]
Domestic Conference
- 髙田拓実, 田中稔之, 上原康平, 田中幹大, Vallet Alexis, Jain Aman, 幡谷龍一郎, 品川政太朗, 今井悠人, 鈴木哲平. Sarashina2.2-OCR:日本語文書解析に特化したエンドツーエンドOCRモデル. 画像の認識・理解シンポジウム (MIRU2026), 2026. [Conference Page]
- 福原大翔, 尾谷圭太, 森友亮, 上原康平, 椋田悠介, 原田達也. 日本語シーンテキスト認識のための実環境画像データセットの構築. 画像の認識・理解シンポジウム (MIRU2026), 2026. [Conference Page]
- 上原康平, 黒瀬優介, 安道健一郎, 村尾晃平, 吉田浩, 田村孝之, 合田憲人, 喜連川優, 原田達也. 推論過程に能動的質問を組み込んだ日本語V&Lデータセットの構築. 画像の認識・理解シンポジウム (MIRU2025), 2025. [Conference Page]
- 勝部駿貴, 福原大翔, 上原康平, 安道健一郎, 椋田悠介, 原田達也. 高品質な日本語マルチモーダルデータセットのスケーラブルな構築手法に関する研究. 画像の認識・理解シンポジウム (MIRU2025), 2025. [Conference Page]
- 髙木尚哉, 上原康平, 椋田悠介, 原田達也. スパイキングニューラルネットワークを利用したVisual Question Answering. 画像の認識・理解シンポジウム (MIRU2025), 2025. [Conference Page]
- 上原康平, 黒瀬優介, 安道健一郎, Chen Jiali, Gao Fan, 金澤爽太郎, 坂本拓彌, 竹田悠哉, Yang Boming, Zhao Xinjie, 村尾晃平, 吉田浩, 田村孝之, 合田憲人, 喜連川優, 原田達也. Asagi: 合成データセットを活用した大規模日本語VLM. 言語処理学会第31回年次大会, 2025. [Paper] [Project Page]
- 森 友亮†, 上原康平† († equal contribution), 原田達也. 視覚・言語融合 Transformer モデルによる画像からの物語文生成. CAI+CAI first workshop(言語処理学会第27回年次大会 ワークショップ), 2021. [Paper]
Others
- NEW Shashank Rao Marpally, Allan Wang, Atharva Ghotavadekar, Renato Alexandre Ribeiro, Nhat Le, Pilar Bachiller-Burgos, Pranav Goyal, Subham Agrawal, Yasuhiro Nitta, Howard Ziyu Han, Daeun Song, Masaki Kuribayashi, Kohei Uehara, Xiyue Wang, Yangzhe Kong, Duc M. Nguyen, Amirreza Payandeh, Gerardo Pérez-González, Alejandro Torrejón-Harto, Jeeho Ahn, Tisha Jain, Andrew Stratton, Elvin Yang, Jorge de Heuvel, Nico Ostermann-Myrau, Sai Anudeep Sajja, Mithilya Raj, Daisuke Sato, Gaston Rouquette, Nikolas Martelaro, Maki Sugimoto, Hironobu Takagi, Chieko Asakawa, Maren Bennewitz, Aaron Steinfeld, Xuesu Xiao, Christoforos Mavrogiannis, Harold Soh. ACME: A Multi-Cultural, Multi-Embodiment Social-Navigation Dataset. arXiv, 2026. [Paper]
- Kohei Uehara, Nabarun Goswami, Hanqin Wang, Toshiaki Baba, Kohtaro Tanaka, Tomohiro Hashimoto, Kai Wang, Rei Ito, Takagi Naoya, Ryo Umagami, Yingyi Wen, Tanachai Anakewat, Tatsuya Harada. Advancing Large Multi-modal Models with Explicit Chain-of-Reasoning and Visual Question Generation. arXiv, 2024. [Paper]
Competitions
- The 5th place in the Visual Question Answering (VQA) Challenge 2018 in CVPR2018. Mikihiro Tanaka, Atsuhiro Noguchi, Kohei Uehara, Lisa Kawai, Yoshitaka Ushiku, Tatsuya Harada [competition page]
Lectures
- Intelligent Informatics - Graduate School of Information Science and Technology, The University of Tokyo, June 6, 2024
Invited Talks
- Kohei Uehara, Antonio Tejero-de-Pablos, Yoshitaka Ushiku and Tatsuya Harada. Visual Question Generation for Class Acquisition of Unknown Objects. FIT, 2019. [Program]
- Kohei Uehara, Antonio Tejero-de-Pablos, Yoshitaka Ushiku and Tatsuya Harada. Visual Question Generation for Class Acquisition of Unknown Objects. MIRU, 2019. [Program]
- Kohei Uehara, Antonio Tejero-de-Pablos, Yoshitaka Ushiku and Tatsuya Harada. Visual Question Generation for Class Acquisition of Unknown Objects. PRMU, 2019. [Program]
Grants & Fellowships
- January 2021 - December 2021 : Microsoft Research Asia Collaborative Research for Ph.D. Student 2021 (D-CORE 2021)
- April 2020 - March 2023 : Japan Society for the Promotion of Science (JSPS) Research Fellowship for Young Scientists (DC1)
Professional Activities
- Organizing Committee Member : MIRU2026 Wakate Program(MIRU2026若手プログラム実行委員), 2026.
- Reviewer : ICCV, CVPR, ECCV, WACV, AAAI, NeurIPS, etc.
Links
Google Scholar Citations
Last update: October 28, 2026